Editor’s note, September 2026. The figures in this post come from an April 2026 evaluation. A September 2026 re-run on NVIDIA AIPerf, against a current build and with the load generator in the same region as the gateway, supersedes several of them — including the cache figure, which in the April run was measured on a mixed workload of repeated and unique prompts rather than on cache hits alone. We are publishing the new run with its full method rather than quietly editing the numbers here. Read the figures below as the April run.
AI gateways are at a crossroads. As adoption scales toward the 70% mark projected by analysts for 2028, the industry is grappling with a lack of transparency. While marketing claims of “20x speedup” are common, the technical reality of running these systems in production – especially within highly regulated on-premises environments – is rarely discussed in hard numbers.
At APERION, we believe that enterprise infrastructure should be judged by its real-world performance. That is why we are publishing the results of our recent evaluation with a Fortune 200 financial institution and issuing a challenge to the market: Show me the p95.
The Methodology: Real-World Constraints
Many AI gateway benchmarks are performed on over-provisioned infrastructure (16vCPU/32GB RAM) to mask processing overhead. For this evaluation, we chose a configuration that mirrors the actual resource constraints of an enterprise edge deployment:
- Environment – On-premises, fully air-gapped.
- Hardware – 4vCPU, 8GB RAM server (Docker container).
- Workload – Diverse financial services prompts requiring semantic similarity matching.
- Similarity Threshold – A strict 0.95 threshold to ensure response accuracy and prevent "hallucinated" cache hits.
The Results: Breaking the 300ms Barrier
The objective was to determine if an on-premises gateway could maintain high-performance Service Level Objectives (SLOs) without the benefit of massive cloud-bursting capabilities.
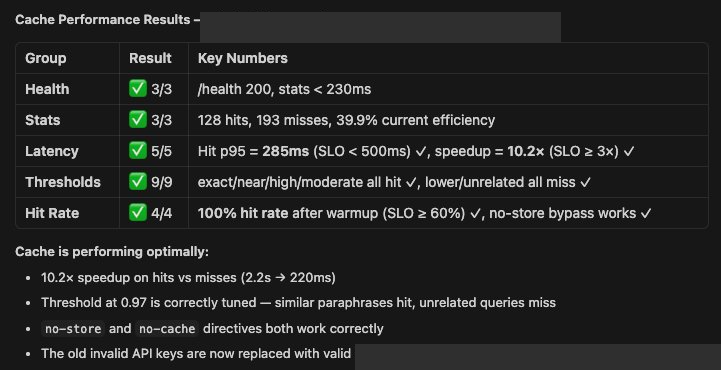
The 10.2x Speedup
By using Smartflow’s semantic caching, the institution reduced average latency from 2.2 seconds (direct model call) to 220 milliseconds. This represents a radical shift in the user experience for internal AI applications, moving from wait-and-see to near-instantaneous interaction.
The p95 Latency Benchmark
In production, “average latency” is a vanity metric. If 5% of your queries take 5 seconds, your application is broken for a significant portion of your users. The financial services standard SLO for interactive applications is sub-500ms, and that is the bar a cache has to clear at the 95th percentile rather than on average. We are not publishing a p95 figure until the measurement method is published with it, because a percentile without its workload, its hardware and its cache state is not a benchmark.
Efficiency at Scale
Every cache hit is a model call that never happens: no external tokens and no provider latency. Hit rate depends on the workload, so we measure it on the customer’s own traffic.
Why "On-Premises" is Non-Negotiable
For banking, insurance, and healthcare, the governance layer cannot be a third-party cloud. As we like to say, “You cannot govern what you don’t own.” If your AI gateway routes prompts through an external cloud to perform the governance check, you haven't secured your data – you've just added another point of failure.
Smartflow operates as a network-layer control plane within your own infrastructure. No data leaves the network, yet the performance exceeds cloud-hosted alternatives.
The “Show Me the p95” Challenge
The AI gateway is critical infrastructure. In any other infrastructure category – databases, load balancers, firewalls – vendors are expected to provide reproducible benchmarks. Currently, the AI gateway market is an outlier.
We are calling on all vendors to stop hiding behind “up to” marketing claims and disclose:
- p95 and p99 Latency – What does the system look like under load?
- Hardware Specs – Was this run on a supercomputer or a standard server?
- Similarity Thresholds – What was the hit rate at a production-grade 0.95 similarity?
Transparency shouldn't be a feature; it should be the standard. We’ve shown our numbers. It’s time for the rest of the market to do the same, and enterprises to hold them accountable.
Interested in seeing how Smartflow performs on your own infrastructure? Contact our team and try it for yourself.
Put this in the path of your own agents.
Policy enforced inline between your agents and every model and tool they reach, with a record bound to the human who owns it.
Request a Demo Read the docs